Scikit-learn has a neural network classifier built in, MLPClassifier. You
do not build the layers yourself, you set the size of the hidden layer and the model
builds it.
The steps are the same as any supervised learning problem, only the fitting is different.
Neural Network Example
In this article we’ll make a classifier using an artificial neural network. The impelemtation we’ll use is the one in sklearn, MLPClassifier.
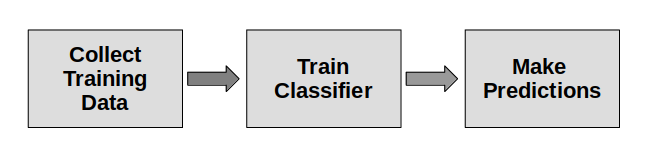
While internally the neural network algorithm works different from other supervised learning algorithms, the steps are the same:
Training data
Any AI algorithm needs data to operate: training data. We start with training data, which consists of two vectors:
| Array | Contains | Size |
| X | training samples represented as floating point feature vectors | size (n_samples, n_features) |
| y | class labels for the training samples | size (n_samples,) |
In code we define that as:
X = [[0., 0.], [1., 1.]]
y = [0, 1]
Where X are measurements and y contains the classes. This is an abstract example, click here to see a detailed example of a neural network.
Train classifier
A classifier is that, given new data, which type of class it belongs to. We then create the neural network classifier with the class MLPClassifier.This is an existing implementation of a neural net:
|
Train the classifier with training data (X) and it’s classes (y):
clf.fit(X, y)
Based on the training data, it can then make predictions.
Predict
One of the key things deep learning and machine learning algorithms do is make predictions. And finally we can make predictions. The classifier will output the class, given the measurements presented to it:
print( clf.predict([[2., 2.], [-1., -2.]]) )
It gives numerical output (0,1,2) that represents a class.
The neural network code is then:
from sklearn.neural_network import MLPClassifier
X = [[0., 0.], [1., 1.]]
y = [0, 1]
clf = MLPClassifier(solver='lbfgs', alpha=1e-5,
                     hidden_layer_sizes=(5, 2), random_state=1)
clf.fit(X, y)
print( clf.predict([[2., 2.], [-1., -2.]]) )
The steps
- Load your data with something like
load_iris()orload_digits(). - Split it with
train_test_split(X, y, test_size=0.2). - Create the model with
MLPClassifier(hidden_layer_sizes=(100, 50)). The numbers are the neurons in each hidden layer. model.fit(X_train, y_train)trains it.model.predict(X_test)gives you the predictions.model.score(X_test, y_test)gives you the accuracy.
Two settings worth changing. max_iter goes up if you see a warning about
convergence, the default of 200 is often too low. alpha is the
regularisation strength, it keeps the network from memorising the training data.
Scikit-learn does no scaling for you here, so put your data through a standard scaler first. A network with one feature from 0 to 10000 and another from 0 to 1 will not learn well.
Reading helps, writing fixes it. PyChallenge has exercises on this and you can try them right now.